AI Wrote Your Workout: Why That's Both a Breakthrough and a Trap
Large language models can generate a training program in seconds. Whether that program is any good depends entirely on who is holding the tool, and why.
Key Points
AI can draft a plausible-looking training program in seconds, but it can instill false confidence of effectiveness in the prompter.
Generic AI models can hallucinate, ignore your training history, not know individual differences, and cannot reliably figure out the effectiveness of training.
Good programming requires individualization, progressive overload, and a positive feedback loop...things a standalone chatbot does not have.
Verro uses AI every day, to enhance training decisions, but how we use use it is an important differentiator.
AI is a powerful tool, but like any powerful tool, it needs an expert hand and a clear intention behind it.
The Prompt That Launched a Thousand Programs
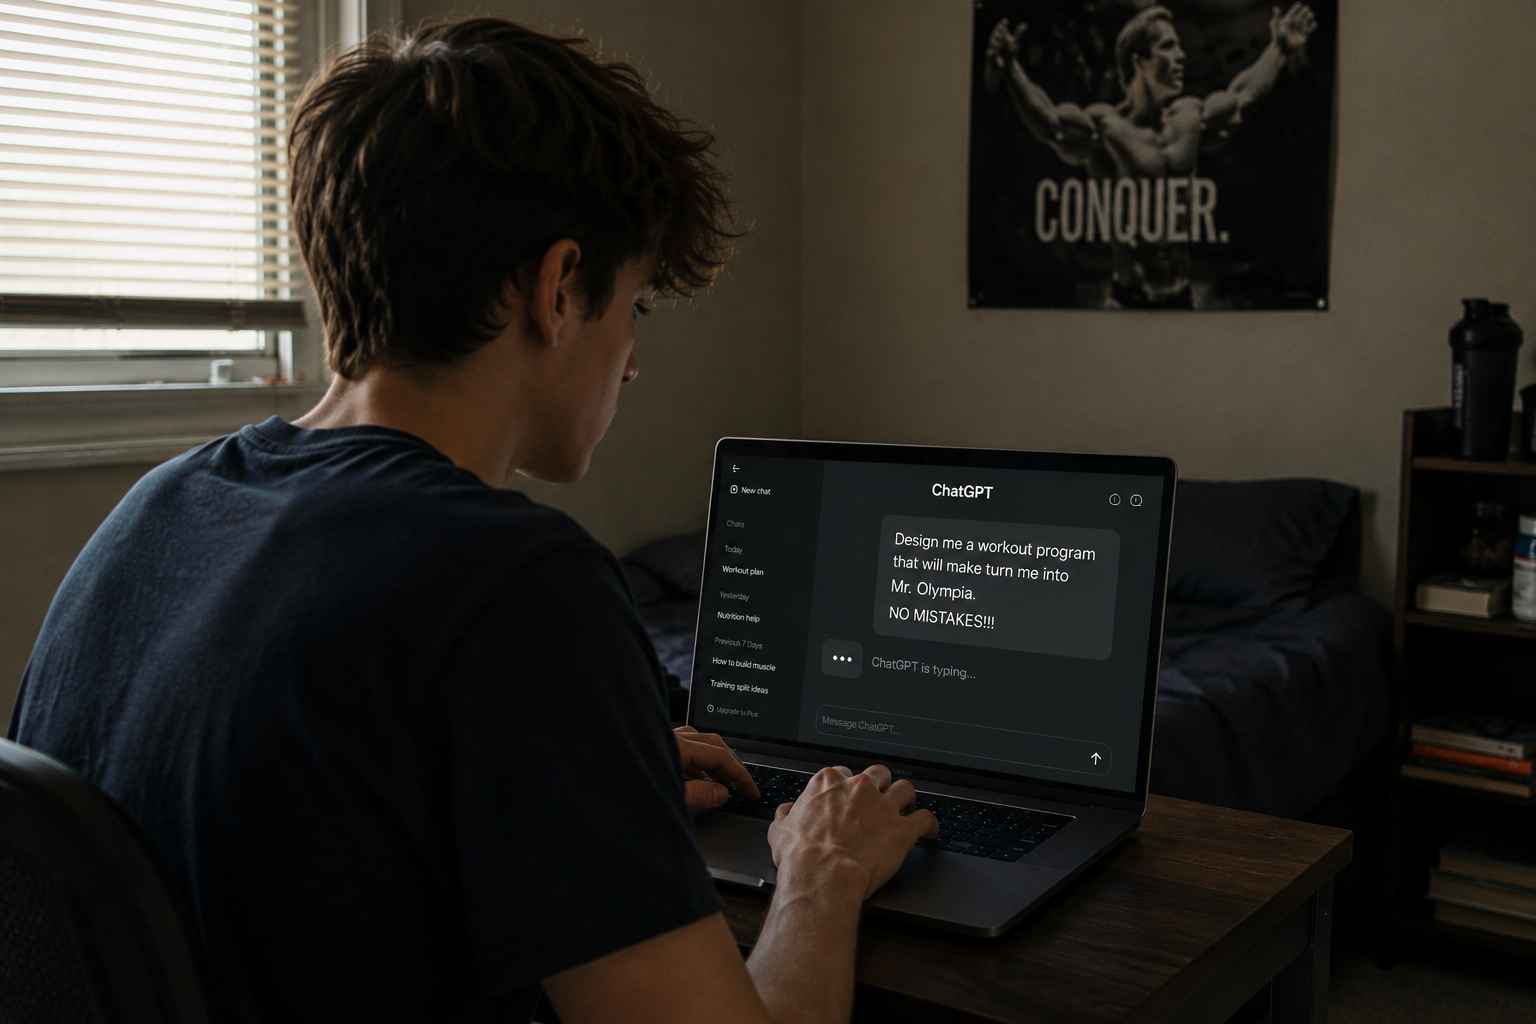
Type "write me a 4-day upper/lower program to build muscle" into any modern AI chatbot and, within about ten seconds, you will get a clean, confident, professional-looking training plan. Sets, reps, exercise selection, a warm-up, maybe even a note about progressive overload. It looks like something a coach charging a few hundred dollars a month would hand you, what a deal!
This is genuinely remarkable. A few years ago, generating something this coherent would have been impossible. And for a lot of people, especially beginners who were previously copying random routines off the internet, an AI-generated program can be seen as a real step up, but I would proceed with a healthy degree of skepticism from any AI workout program. I want to be clear about that from the start: I am not here to tell you AI is bad at fitness. I use it every day.
But there is a gap between a program that looks right and a program that is right for you. That gap is where things can go wrong. And understanding it is the difference between using AI as a genuine advantage and being quietly misled by a very articulate machine.
At Verro, we have thought about this more than most, because we build AI directly into how we coach. So this post is two things at once: an honest look at what breaks when you let a chatbot write your training, and a transparent account of how we use the same technology without falling into those traps.
How People Are Actually Using AI to Program
The pattern is consistent. Someone opens a general-purpose chatbot and asks it to build a program. Sometimes the prompt is detailed (goals, days available, equipment, injury history), sometimes it is a single sentence. The model responds instantly with a full mesocycle. The person follows it, or follows it for a couple of weeks, then goes back and asks for "a harder version" or "something for my shoulders."
What makes this so appealing is obvious. It is free (or nearly free), it is instant, it never judges you, and the output is fluent. Compared to paying for coaching or wading through conflicting advice on social media, it can feel like a cheat code.
And for the most basic scenarios, it often is good enough. A total beginner doing almost any structured resistance training with progressive overload will improve. The novice adaptation window is forgiving. The problem is that the very things AI does well (producing a confident, generic, reasonable-sounding template) are not the things that separate a mediocre training outcome from a great one, and may not be thinking about long-term progress and injury prevention.
What Good Programming Actually Requires
To see where AI falls short, you have to be specific about what real programming involves. It is not just picking exercises and rep ranges. Decades of resistance-training research point to a few non-negotiables.
Volume, calibrated to the individual. Training volume, the number of hard sets per muscle group per week, is the primary driver of hypertrophy, and it follows a dose-response curve (Schoenfeld, Ogborn & Krieger, 2017). But the useful dose is not universal. The right weekly volume for a given muscle depends on training age, recovery capacity, and how that specific person responds. What is optimal for one lifter is junk volume or overtraining for another.
Progressive overload, managed over time. The American College of Sports Medicine's position stand on progression (ACSM, 2009; Kraemer & Ratamess, 2004) is explicit that adaptation requires systematically increasing demands, and that the progression must be periodized rather than linear-forever. That means the program has to change in response to what happened, not just escalate on a fixed schedule.
Individual response variability. This is the part most people underestimate. In the classic Hubal et al. (2005) study of 585 people running the identical resistance program, the change in arm strength ranged from 0% to over 250%. Same program, wildly different results. There is no such thing as an optimal program in the abstract, only an optimal program for a specific person at a specific time, discovered partly through trial and adjustment.
A feedback loop. Coaching is not a one-time act of writing a plan. It is a cycle: prescribe, observe the result, adjust. Auto-regulation tools like RPE and reps-in-reserve exist precisely because the plan on paper must bend to how the athlete actually performs on the day (Helms et al., 2016). Without the loop, you are guessing. Novice lifters often struggle with form or judging proper intensity, which can make it difficult to know how and when to progressively overload.
Where AI Goes Wrong When It Writes Your Training
Now overlay those requirements onto what a general-purpose language model actually does, and the failure modes become clear.
It hallucinates with total confidence. Language models generate fluent text by predicting likely word sequences, not by checking facts. Hallucination, the production of confident but false information, is a well-documented and inherent property of these systems (Ji et al., 2023). In a fitness context this shows up as invented "optimal" set counts, fabricated citations, made-up exercise variations, and physiologically dubious claims delivered in the same authoritative tone as everything else. Systematic reviews of ChatGPT in healthcare have flagged exactly this: fluent output, variable and sometimes unsafe accuracy (Sallam, 2023).
It cannot see you. A standalone chatbot has no record of what you lifted last week, no estimate of your one-rep max trend, no idea whether your last block stalled or your knee has been aching. Every conversation starts from near-zero context. It is, structurally, incapable of the feedback loop that real programming depends on.
It regresses to the generic. Because these models are trained to produce the most statistically likely response, they gravitate toward the average of the internet. That means the same middle-of-the-road template for a rank beginner and an advanced lifter, and a strong pull toward whatever was most common in the training data rather than what is right for you. Researchers examining generative AI in sport and exercise science have raised precisely this concern about uncritical, homogenized output (Dergaa et al., 2023; Washif et al., 2024).
It has no stake in the outcome and no way to verify it. If the program does not work, the model does not find out. There is no mechanism by which the failure feeds back and improves the next prescription for you specifically.
| What good programming needs | General-purpose chatbot, on its own |
|---|---|
| Volume calibrated to your recovery | Generic set counts from the training-data average |
| Progression driven by last week's results | No memory of last week |
| Accounting for individual response | One template, applied to everyone |
| A prescribe-observe-adjust feedback loop | Writes the plan, then disappears |
| Verifiable, factual claims | Fluent output, prone to confident hallucination |
Full Transparency: Yes, Verro Uses AI
Here is the part where a lot of companies get cagey. We are not going to. Verro uses artificial intelligence extensively, and we think you deserve to know exactly where and how.
A few years ago, I reached out to a team of software engineers about building out some custom software for Verro based on projects I have been imagining for almost a decade based around capturing and using fitness information. They quoted me around $50,000 just for the discovery phase and very likely another $100,000 for a minimum viable product. Needless to say, that was out of my budget as someone who just dumped their life savings into a concept gym based in Los Angeles. Today, I have been able to make that minimum viable product for a fraction of that initial cost using AI, and honestly I think it's better than anything they could have made for me.
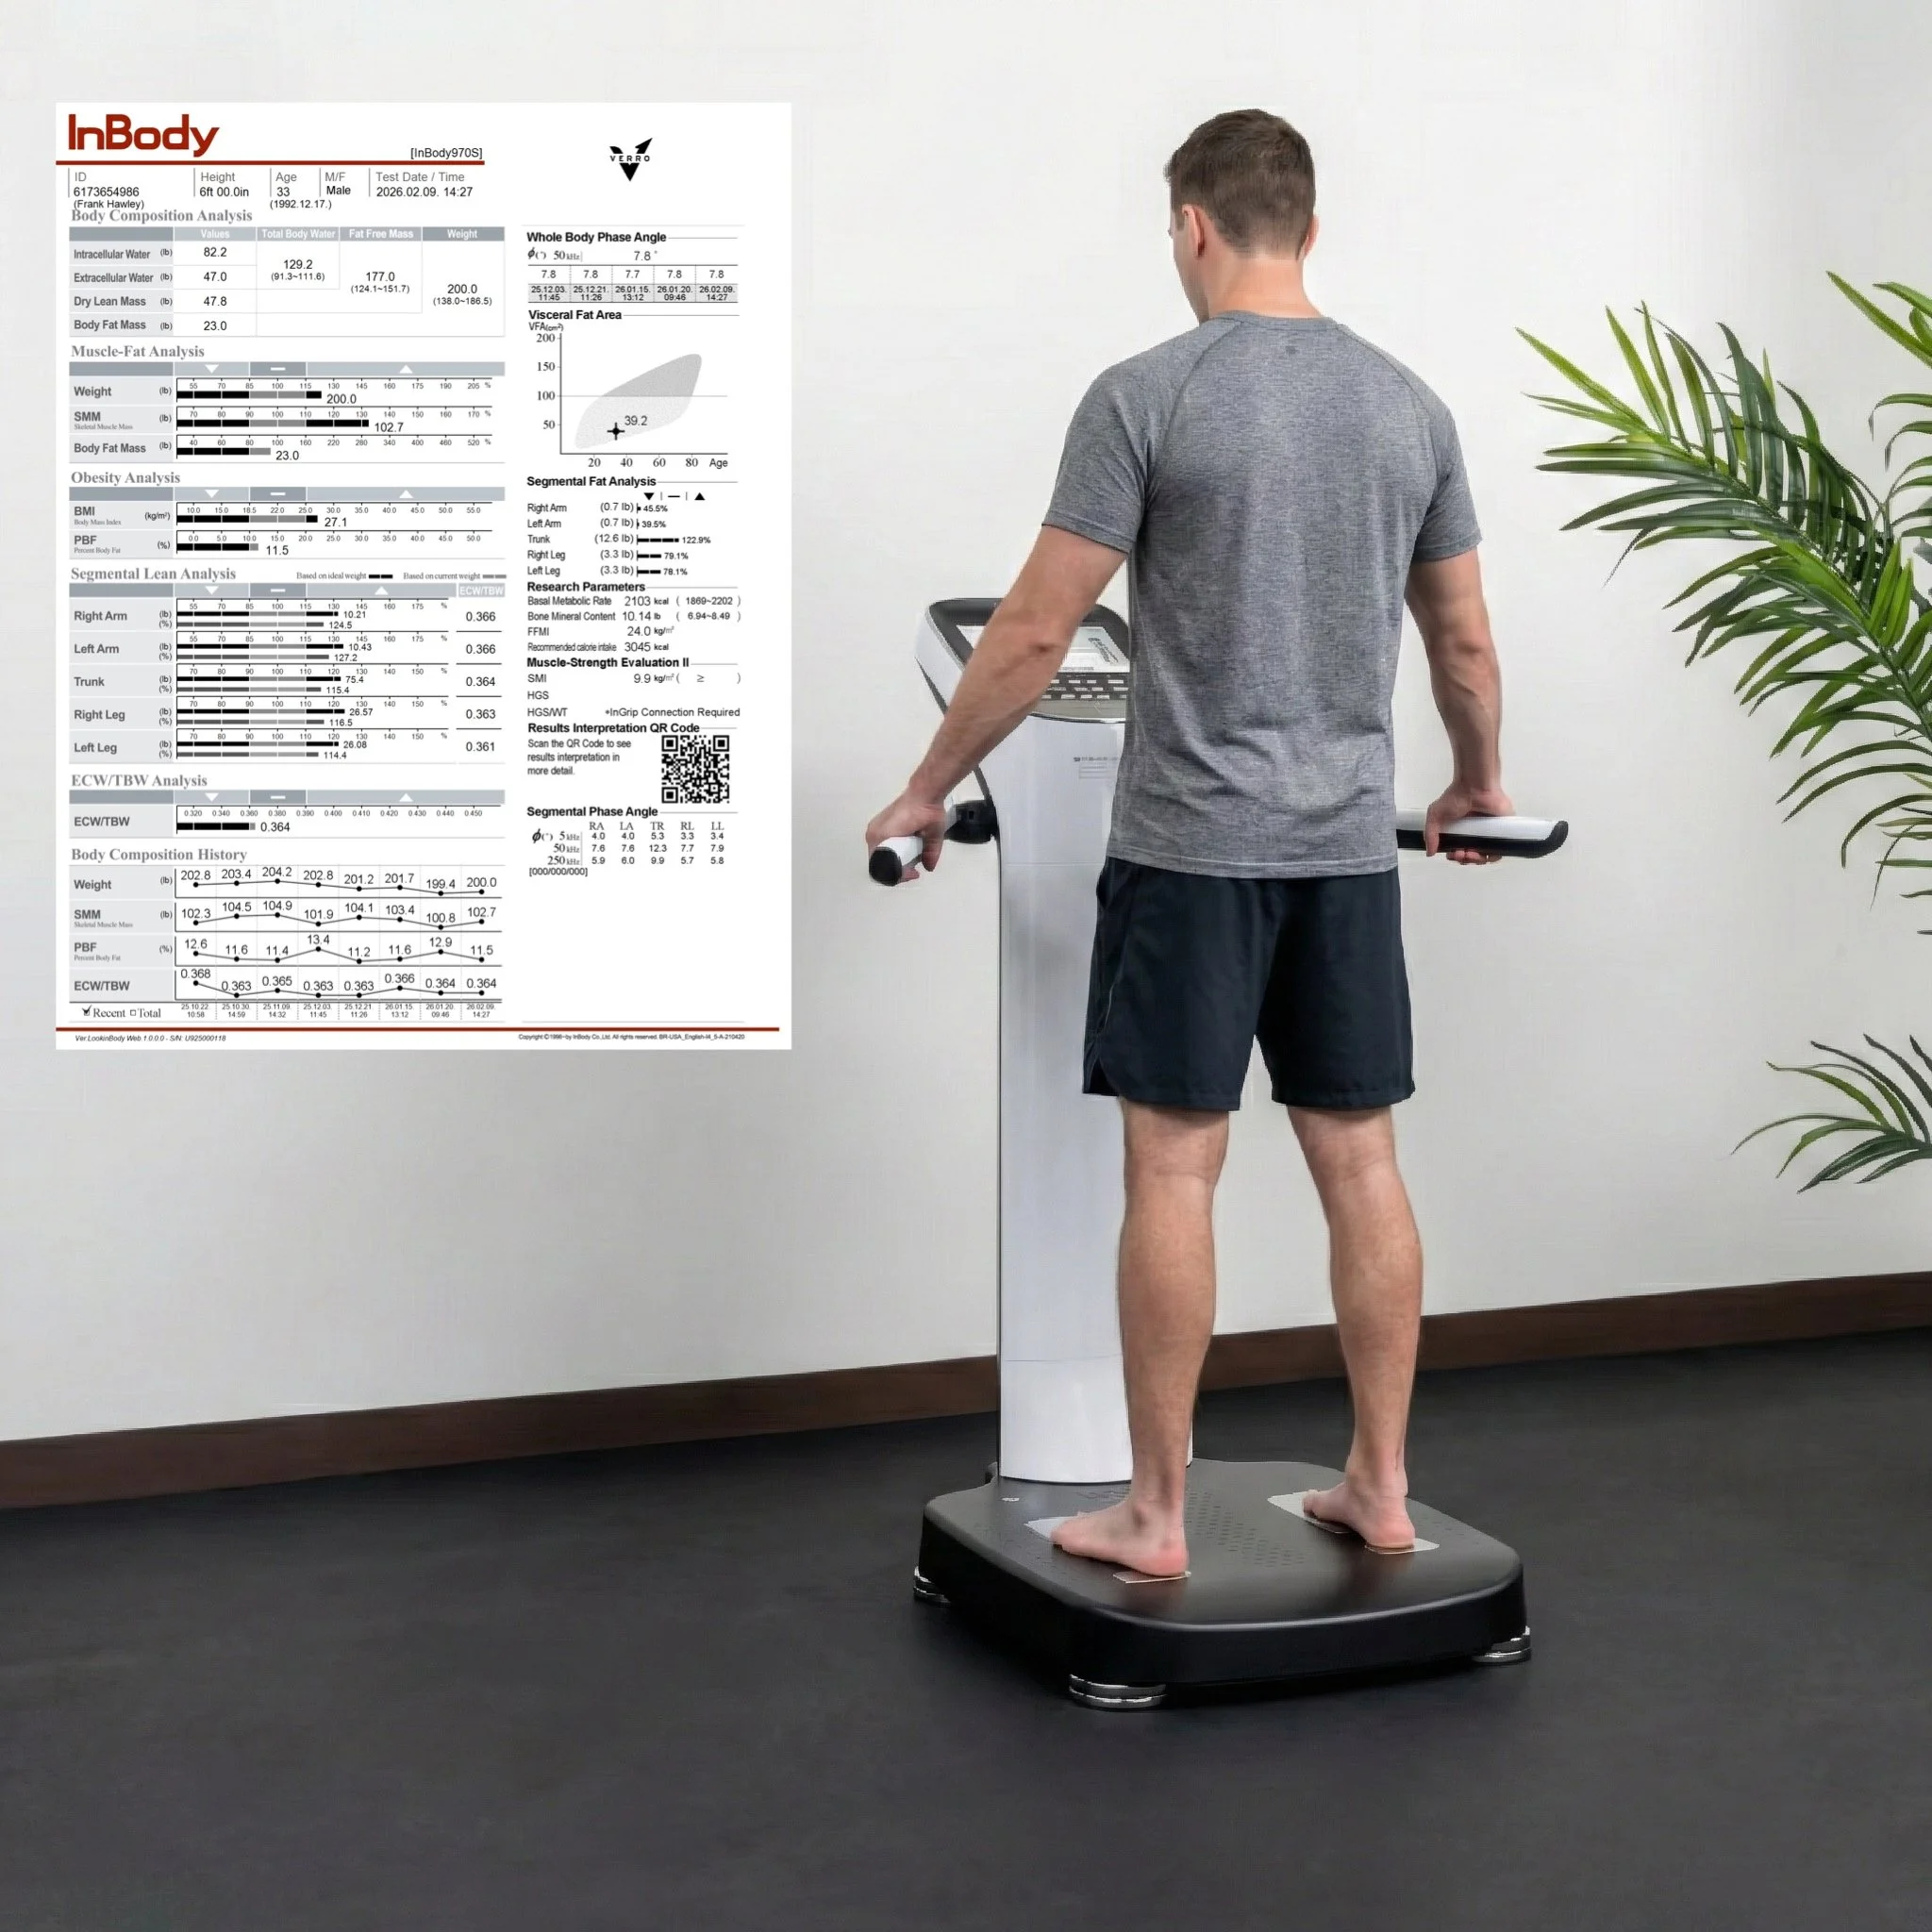
Today at Verro, AI helps us generate the narrative summaries on assessment reports. It assists with parsing InBody scans and body-composition data. It powers parts of our content and education tools. And large language models help us reason about training data at a scale that would be impractical by hand. This is not a footnote in how Verro works. It is woven through the platform.
We are telling you this plainly for the same reason we publish our reasoning in these blog posts: if we are going to argue that AI must be used honestly and with clear intention, we have to hold ourselves to that standard first. Using AI is not the problem. Using it carelessly, or hiding that you use it at all, is.
How We Use AI at Verro
The difference between what we do and what happens when you ask a chatbot to write your program is not the technology. It is the same underlying models. The difference is the structure around the model: the expert in the loop, the real data feeding in, and a clear intention governing every use.
We feed it your actual data, not a blank prompt. Verro's AI does not guess in a vacuum. It works on top of your logged sessions, your estimated 1RM trends across programs, your set-by-set history, and your body-composition scans. When it reasons about your training, it is reasoning about you, not about the average lifter on the internet. That alone eliminates most of the "it cannot see you" failure mode.
We keep a human expert in the loop, always. AI at Verro drafts, summarizes, and surfaces patterns. It does not have the final say on your training. A coach reviews the output, sanity-checks it against our expertise from years in the field, and makes the call. The model is an assistant to an expert, never a replacement for one. This is the single most important safeguard against hallucination: someone who knows the domain is checking the work.
We constrain it with real frameworks, not vibes. Our systems are built around established, evidence-based structures. Personalized volume landmarks (our DTV/MV/MEV/MAV/MRV model, which uses Bayesian shrinkage from population research priors toward your own data). An RPE-based estimated-1RM formula applied consistently across programs. A fitness-fatigue model built from your daily training stress. The AI operates inside these guardrails. It is not free-associating about sets and reps; it is working within a framework grounded in the same literature we cite in these posts.
We build the feedback loop that a chatbot lacks. Because your data flows back in continuously, the system can actually tell whether last block worked. Your e1RM trend on the Exercise History chart is not a guess, it is computed from what you lifted. When we adjust volume or intensity, we are responding to evidence, closing exactly the loop that a one-shot AI prompt leaves open.
The Real Principle: A Powerful Tool Needs an Expert and an Intention
Strip away the specifics and this is the whole argument. AI is a power tool. A nail gun builds houses faster than a hammer, and it also sends people to the emergency room. The tool did not change; the outcome depends entirely on who is holding it and what they are trying to do.
A domain expert with a clear intention uses AI to move faster on things they already understand. They can spot the hallucination, because they know what correct looks like. They know when the generic answer is fine and when it is dangerous. They bring the goal, the judgment, and the accountability. The model brings speed and scale.
A non-expert with a vague intention gets something different: a fluent, confident output they have no way to evaluate, applied to a body they do not fully understand, with no mechanism to catch when it goes wrong. The very fluency that makes AI feel trustworthy is what makes it dangerous in untrained hands.
This is why we do not think "does it use AI?" is the right question to ask about any fitness tool, including ours. The right questions are: Whose data is it using? Who is checking its work? What framework constrains it? And what is it actually trying to accomplish for you?
Limitations and Honesty
A few honest caveats. First, the research on AI-generated training programs specifically is still young. Most of what we can cite examines large language models in adjacent domains (academic writing, healthcare advice, general sport-science applications) rather than head-to-head trials of AI-written versus coach-written programs producing measured strength or hypertrophy outcomes. That evidence largely does not exist yet, and anyone claiming a definitive verdict is getting ahead of the data.
Second, these models improve quickly. Some limitations described here are being actively worked on across the industry, and specific failure modes may soften over time. The structural point, that a tool without your data and without a feedback loop cannot individualize, is more durable than any particular model's current weakness.
Third, we are not a neutral party. We built an AI-assisted coaching platform, so we have an obvious interest in the conclusion that AI plus expert oversight beats AI alone. We have tried to argue it from the evidence rather than from our own convenience, but you should weigh the source, as you should with any company writing about its own product.
Practical Takeaways
Treat AI output as a draft, not a prescription. A chatbot program is a reasonable starting hypothesis. It is not a plan validated against your body.
Give it your data, or accept generic results. Without your training history and results, any model is guessing from the internet average. The more real context, the better the output.
Never outsource the feedback loop. The value of coaching is in the weekly adjustment. If nothing is watching whether last week worked, the program is flying blind.
Verify anything that sounds like a fact. Confident set numbers, cited studies, and physiological claims from a general chatbot should be checked. Fluency is not accuracy.
Ask who is holding the tool. The useful question is not whether a product uses AI, but whose data it runs on, what framework bounds it, and whether an expert is accountable for the result.
References
| Citation (APA) | Study Type | Why It Matters | Supports This Claim |
|---|---|---|---|
| Ji, Z., et al. (2023). Survey of Hallucination in Natural Language Generation. ACM Computing Surveys, 55(12), 1-38. | Systematic review | Definitive survey establishing hallucination as an inherent property of generative language models. | AI produces confident but false information, including in fitness contexts. |
| Sallam, M. (2023). ChatGPT Utility in Healthcare Education, Research, and Practice: Systematic Review. Healthcare, 11(6), 887. | Systematic review | Reviews benefits and risks of ChatGPT in health, flagging variable and sometimes unsafe accuracy. | Fluent AI health output can be inaccurate and requires expert verification. |
| Dergaa, I., Chamari, K., Zmijewski, P., & Ben Saad, H. (2023). From human writing to artificial intelligence generated text: examining the prospects and potential threats of ChatGPT. Biology of Sport, 40(2), 615-622. | Review | Sport-science-focused analysis of generative AI's promise and its tendency toward uncritical, homogenized output. | General-purpose AI regresses toward generic, average content in sport contexts. |
| Washif, J.A., et al. (2024). Artificial Intelligence in Sport and Exercise Science: Perspectives and Applications. International Journal of Sports Physiology and Performance, advance online. | Review | Surveys where AI adds value in sport science and where human oversight remains essential. | AI is a valuable assistant in sport science but is not a substitute for expert judgment. |
| Schoenfeld, B.J., Ogborn, D., & Krieger, J.W. (2017). Dose-response relationship between weekly resistance training volume and increases in muscle mass. Journal of Sports Sciences, 35(11), 1073-1082. | Meta-analysis | Establishes volume as the primary hypertrophy driver, following a dose-response curve. | Effective training volume is individual, not a universal number a chatbot can assume. |
| Hubal, M.J., et al. (2005). Variability in muscle size and strength gain after unilateral resistance training. Medicine & Science in Sports & Exercise, 37(6), 964-972. | Experimental (N=585) | Identical program, response ranging from ~0% to >250%. The definitive demonstration of individual variability. | There is no optimal program in the abstract, only for a specific individual. |
| Kraemer, W.J., & Ratamess, N.A. (2004). Fundamentals of resistance training: progression and exercise prescription. Medicine & Science in Sports & Exercise, 36(4), 674-688. | Review | Foundational account of how progression must be systematically managed over time. | Progressive overload must adapt to results, not escalate on a fixed schedule. |
| American College of Sports Medicine. (2009). Progression Models in Resistance Training for Healthy Adults. Medicine & Science in Sports & Exercise, 41(3), 687-708. | Position stand | Consensus guidelines requiring periodized, individualized progression. | Sound programming requires periodization and individualization a one-shot AI lacks. |
| Helms, E.R., Cronin, J., Storey, A., & Zourdos, M.C. (2016). Application of the Repetitions in Reserve-Based RPE Scale for Resistance Training. Strength & Conditioning Journal, 38(4), 42-49. | Applied review | Formalizes auto-regulation, adjusting the plan to daily performance. | Real programming depends on a prescribe-observe-adjust feedback loop. |
| Suchomel, T.J., Nimphius, S., Bellon, C.R., & Stone, M.H. (2018). The Importance of Muscular Strength: Training Considerations. Sports Medicine, 48(4), 765-785. | Review | Details the deliberate, individualized decision-making behind effective strength programming. | Effective programming is expert decision-making, not template selection. |
DISCLAIMER
This article is for educational purposes only and is not intended as medical or individualized training advice. AI-generated training programs, including those produced with expert oversight, cannot account for every aspect of your health, injury history, or medical status.
The limitations of large language models described here reflect their behavior as of writing and are an active area of development; individual responses to any training program vary substantially. Nothing here should be taken as a claim that AI-assisted programming guarantees a particular result.
Consult a qualified healthcare or fitness professional before beginning or significantly changing a training program, especially if you have an injury or medical condition. At Verro, we use AI as a supervised assistant to expert coaching. one powerful tool within a larger, evidence-based process. not as a standalone replacement for professional judgment.